Quick Section Index
- 1.Introduction: The Modern Data Engineer Toolkit in 2026
- 2.1. Advanced Python Programming & AsyncIO
- 3.2. Advanced SQL, Partitioning & Query Tuning
- 4.3. Apache Spark & PySpark Distributed Processing
- 5.4. Multi-Cloud Data Platforms (AWS, Azure, GCP)
- 6.5. Cloud Data Warehouses (Snowflake, BigQuery, Redshift)
- 7.6. Workflow Orchestration with Apache Airflow
- 8.7. Real-Time Event Streaming with Apache Kafka
- 9.8. Dimensional Data Modeling (Star & Snowflake Schemas)
- 10.9. Data Lakehouse Formats (Delta Lake, Iceberg, Hudi)
- 11.10. Generative AI Data Pipelines & Vector Databases
- 12.Master These Skills at JVM Institute Pune
Introduction: The Modern Data Engineer Toolkit in 2026
The enterprise technology landscape has undergone a dramatic transformation. Modern data environments are no longer confined to static nightly SQL scripts running on legacy on-premise servers. Today, modern companies process real-time streaming telemetry, multi-cloud data lakes, vector embeddings for LLMs, and petabyte-scale distributed data warehouses.
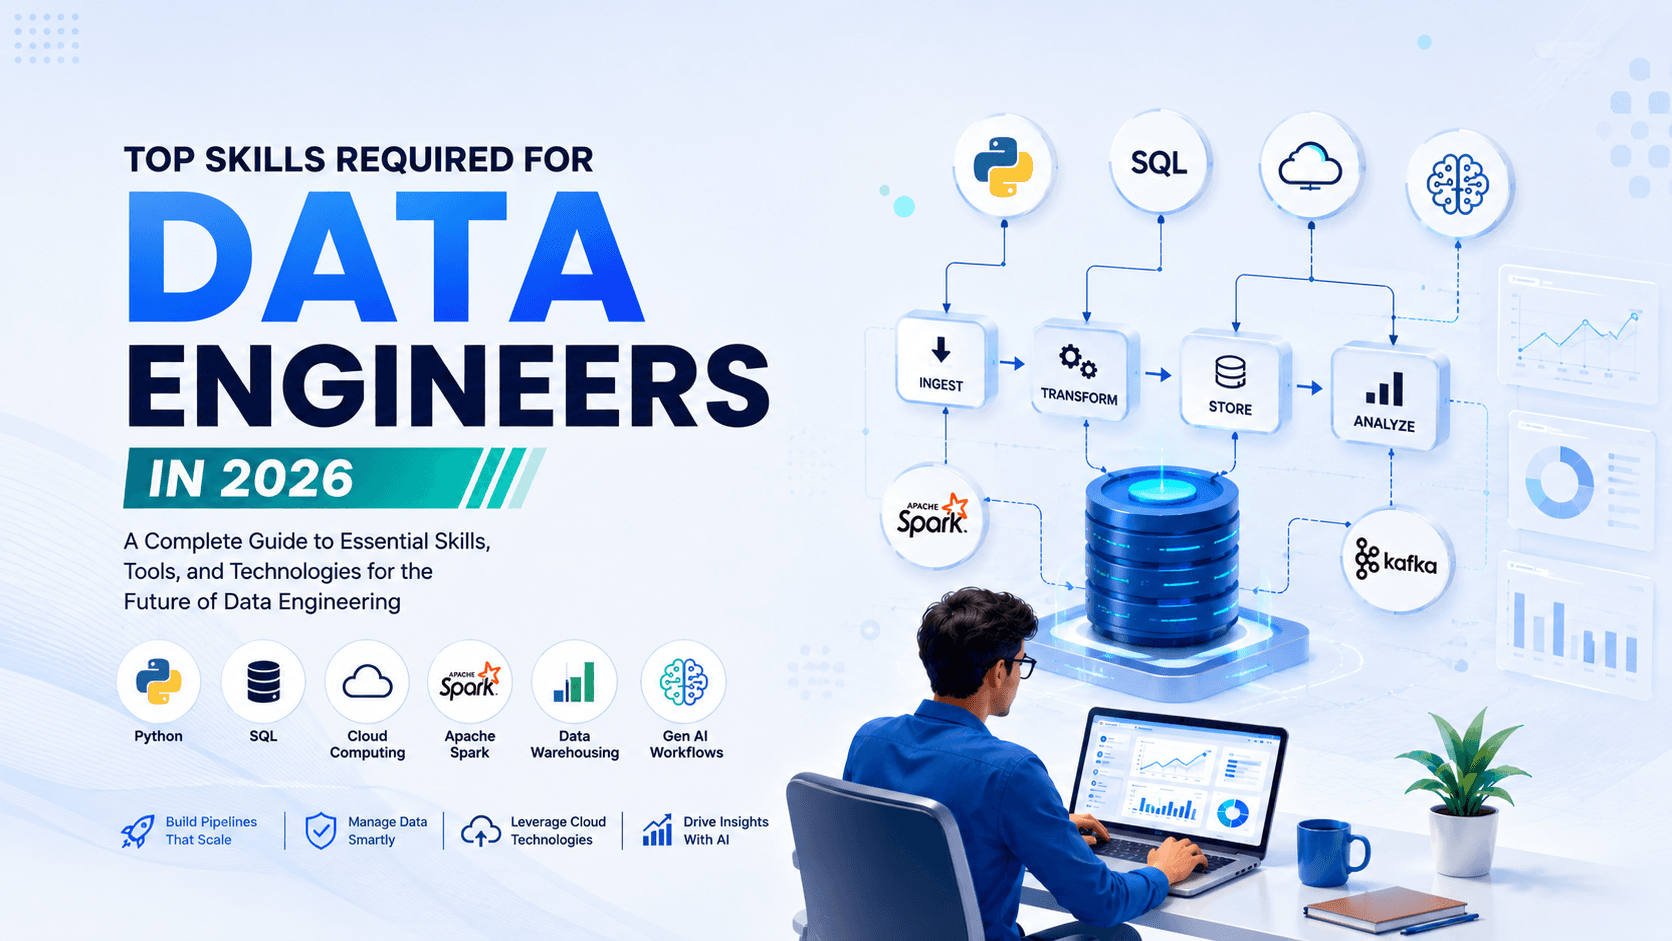
To remain highly competitive and secure top-tier salary offers in 2026, Data Engineers must master a versatile technical toolkit spanning programming, distributed computing, cloud architecture, workflow orchestration, and emerging Generative AI pipelines.
Whether you are a computer science student starting from scratch or a software developer pivoting into big data, this definitive guide provides a deep analytical walkthrough of the 15 essential skills required for Data Engineers in 2026.
1. Advanced Python Programming & AsyncIO
Python remains the uncontested #1 programming language in Data Engineering. It serves as the primary language for writing ETL scripts, custom Apache Airflow operators, PySpark transformations, REST API integrations, and cloud lambda triggers.
2. Advanced SQL, Partitioning & Query Tuning
SQL is the universal language of data manipulation. Every professional Data Engineer must write highly optimized queries, analyze query execution plans, manage indexes, handle window functions, and structure complex CTEs (Common Table Expressions).
3. Apache Spark & PySpark Distributed Processing
When dataset sizes exceed single-machine memory (RAM), traditional Pandas scripts fail with Out-Of-Memory (OOM) errors. Apache Spark solves this via in-memory distributed data processing across cloud worker nodes.
4. Multi-Cloud Data Platforms (AWS, Azure, GCP)
Over 90% of enterprise data infrastructures live on public cloud platforms. Data Engineers must design scalable cloud architectures using serverless and managed services.
5. Cloud Data Warehouses (Snowflake, BigQuery, Redshift)
Modern data engineering relies heavily on cloud-native data warehouses decoupled for independent compute and storage scaling.
6. Workflow Orchestration with Apache Airflow
Manual script scheduling via Cron is prone to silent failures. Data Engineers use Apache Airflow to orchestrate, schedule, and monitor complex Directed Acyclic Graphs (DAGs) as native Python code.
7. Real-Time Event Streaming with Apache Kafka
For applications requiring sub-second transaction tracking (e.g., fraud detection, ride-hailing location tracking), Apache Kafka acts as the high-throughput pub/sub event bus.
8. Dimensional Data Modeling (Star & Snowflake Schemas)
Designing optimal database schemas for analytics. Data Engineers must understand dimensional modeling, Fact tables, Dimension tables, and Slowly Changing Dimensions (SCD Type 1, 2, 3).
9. Data Lakehouse Formats (Delta Lake, Iceberg, Hudi)
Combining the cheap storage of Data Lakes with the ACID transaction guarantees of Data Warehouses using open table formats like Apache Iceberg, Delta Lake, and Hudi.
10. Generative AI Data Pipelines & Vector Databases
Building data pipelines that chunk unstructured text, generate vector embeddings (OpenAI/HuggingFace), and index data into Vector Databases (Pinecone, ChromaDB, Milvus) for Retrieval-Augmented Generation (RAG).
Master These Skills at JVM Institute Pune
Gain hands-on mastery over Python, SQL, Apache Spark, Snowflake, Airflow, and Cloud AWS/Azure under the mentorship of senior data architects. Complete live production portfolio projects and secure top placement opportunities.

JVM Technical Team
Published by senior IT faculty members and industry lead architects at JVM Institute Pune. Dedicated to empowering students with real-world Data Engineering, AI/ML, PySpark, and Cloud computing expertise.